




Personal AI Launches MODEL‑4, Building Personal Intelligence Directly Into the Network

FREE Breaking News Alerts from StreetInsider.com!
StreetInsider.com Top Tickers, 10/23/2026
- Wall St dips after AI-led selloff; SpaceX worries hit telecoms
- Meta's capital-raising plans expose a major weakness in the AI boom
- Brent crude hits more than five-month high on Houthi-Saudi attacks, UAE oil spill
- BofA flags further downside risk for stocks, yields and dollar
- SpaceX cell-site ambitions lift tower stocks and weigh on carriers
 Tweet
 Share
 E-mail
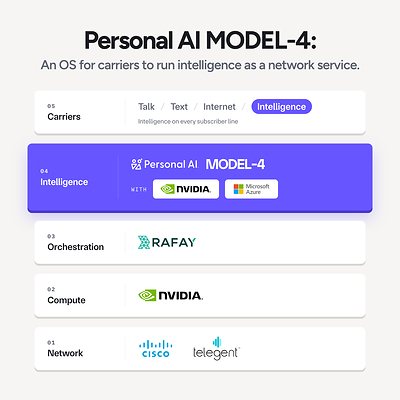
An Operating System (OS) that lets telecommunications operators deliver personal intelligence to every subscriber, billed alongside talk, text, and data. MODEL‑4 brings together the critical layers of AI delivery with NVIDIA, Microsoft, Rafay, Cisco, and Telegent.
AI is moving beyond centralized applications and onto the network in a deliberate, democratized shift. Carriers are uniquely positioned to deliver this next generation of intelligence; they already have direct relationships with nearly every individual and business worldwide, a trusted and secure identity for every line, an existing billing relationship, and a distributed network footprint. More than an AI model, MODEL‑4 delivers the missing personal intelligence layer. It combines proprietary memory, unique identity, on-network inference, and multi-modal agents into a new service delivered on every line.
"Carriers connected the world through talk, then text, then the internet. Intelligence is the next connectivity, and carriers are the ones best placed to deliver it," stated
MODEL‑4: The OS for personal intelligence on the network
MODEL‑4 brings together the core capabilities operators need to run personal intelligence as a network service:
- Personal memory: A persistent personal model for each subscriber that remembers, learns, and evolves over time, tied to the subscriber and their line.
- Network identity: The subscriber's SIM and phone number serve as the agent's identity, eliminating the need for a separate app or login.
- On-network small language models: Tier‑1 SLMs handle about 95% of traffic inside the operator's network, routing only complex requests to larger models for greater efficiency and better economics.
- Voice and text agents: Subscribers can utilize agents through the communication channels they already use, including native calls and texts.
- Token plans: Operators can package and bill intelligence alongside existing talk, text, and data plans.
Building on Intelligence Everywhere orchestration research conducted with NVIDIA and Comcast, MODEL‑4 delivers 16 ms time-to-first-token, 405 milliseconds end-to-end voice latency, and a cost of
Turning AI into a network service with token plans
Token plans give carriers three paths to generate new revenue from personal intelligence:
- Native: A token pool included in the subscriber's plan powers carrier-native agents for call handling, missed calls, messaging on the subscriber's behalf, proactive reminders, and other everyday services, generating consumer revenue with no third party required.
- Aggregation: For requests requiring deeper reasoning or web search, the agent can route to leading LLM providers, and the carrier bills those AI platforms for access.
- Agent Store: Personal agents can transact with enterprise service agents for services such as rides, reservations, and banking without requiring the user to open an app, enabling the carrier to take a share of each transaction.
Personal AI projects that a personal agent on every line can lift ARPU across an operator's entire subscriber base. Because subscriber memory stays on the network under existing CPNI protections or country-specific laws, carriers can offer these services within the privacy framework they already operate.
Built for the carrier ecosystem
MODEL‑4 plugs into the stack operators already run. NVIDIA accelerates inference, Microsoft Azure Local keeps data on-premises, and Cisco optimizes the network. Rafay orchestrates deployment across core and edge, and Telegent unifies carrier voice, messaging, and cellular with business communications. The result is personal intelligence delivered as a native network service.
NVIDIA provides the accelerated computing infrastructure that enables MODEL‑4 to move AI inference from centralized data centers into the network, closer to where subscribers live and work.
Personal AI MODEL‑4 utilizes Multi-Instance GPU (MIG) partitioning on NVIDIA RTX PRO 6000 Blackwell servers (96 GB VRAM) in close collaboration with NVIDIA to isolate workloads, hosting up to 40 distilled small language model instances alongside ASR and TTS lanes per GPU slice to ensure predictable sub-second latency and zero cross-tenant interference. Building upon this hardware foundation, the platform integrates NVIDIA components such as NeMo Retriever Nemotron VL models (llama-nemotron-embed-vl-1b-v2 and llama-nemotron-rerank-vl-1b-v2) for dense embeddings and reranking, vLLM-served LLMs with upgrade paths to LLM NIM, and Parakeet-0.6B for speech-to-text processing.
"Voice is the most native application for telecom providers," said
Microsoft Azure Local extends Azure capabilities to infrastructure the operator runs in its own network. Running MODEL‑4 on Azure Local lets operators keep subscriber memory and data on-premises, under the same controls that govern their other subscriber information.
"Telecommunications operators are increasingly looking to run critical AI workloads closer to where data is generated, while maintaining the security, control, and consistent management they expect from Azure," said
Rafay provides infrastructure orchestration that automates how MODEL‑4 is provisioned and operated across operator and edge environments, reducing deployment time from years to weeks.
"Operators shouldn't spend years putting AI into production. Rafay's orchestration with MODEL‑4 takes that down to weeks," said
Cisco brings the mobility and network infrastructure deployed across many of the world's largest carrier networks, optimizing those networks for intelligence as a new class of traffic.
"Cisco already sits at the heart of the world's carrier networks. Together with Personal AI, we're actively exploring how networks can be tuned to support distributed intelligence, enabling operators and partners to deliver AI with the performance and reliability subscribers expect," stated
Telegent is building the first native AI mobile network platform, unifying
"The mobile number is still the most trusted identity people have, and calls and texts are still how they reach the people and businesses that matter to them," said
The OS for personal intelligence
The next generation of AI will not be defined by more intelligent models but by how intelligence becomes personal.
MODEL‑4 gives operators an OS to deliver personal intelligence as a network service: intelligence that remembers, learns, and carries context across experiences, becoming more personal and valuable over time.
For subscribers, that means AI that knows them and anticipates their needs. For carriers, it introduces a brand-new category of service – a new driver of value from the relationships, infrastructure, and trust they already own.
Media Contacts
[email protected]
[email protected]
 View original content to download multimedia:https://www.prnewswire.com/news-releases/personal-ai-launches-model4-building-personal-intelligence-directly-into-the-network-302914421.html
SOURCE Personal AI
Serious News for Serious Traders! Try StreetInsider.com Premium Free!
You May Also Be Interested In
- Cuttable Unveils Next-Generation AI Advertising Platform as U.S. Expansion Accelerates
- Verisk Comments on Delaware Supreme Court Order Regarding AccuLynx
- Ascend Cleaning passes 1,000 homes cleaned in bid to become the best cleaning service in Los Angeles
Create E-mail Alert Related Categories
PRNewswire, Press ReleasesSign up for StreetInsider Free!
Receive full access to all new and archived articles, unlimited portfolio tracking, e-mail alerts, custom newswires and RSS feeds - and more!
